Block Your Ears and Talk
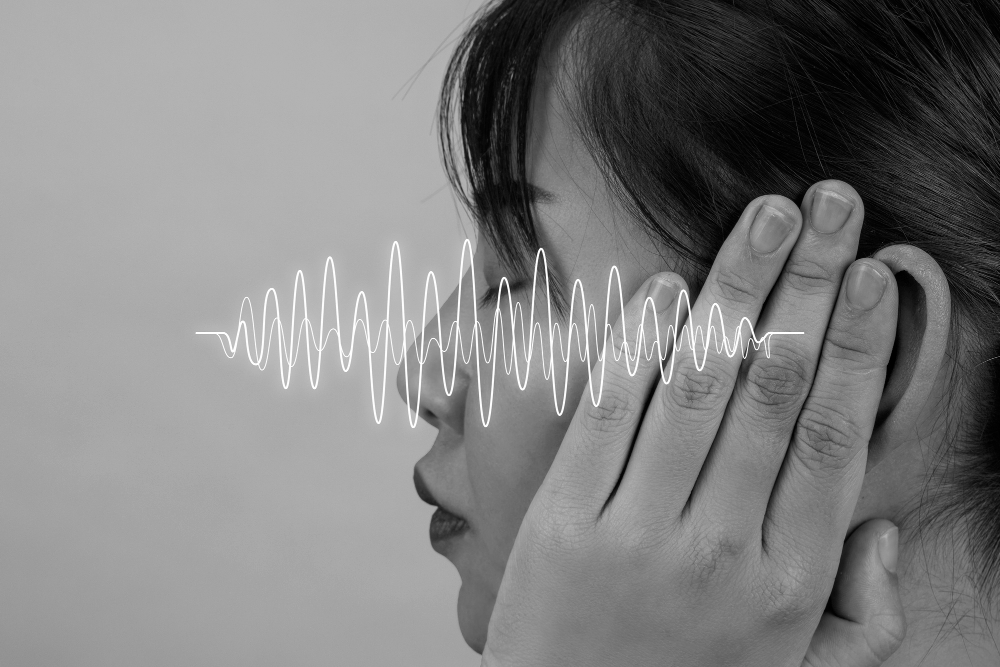
Put a finger firmly in each ear so that the canals are properly closed, and then say something out loud.
Your voice does not go quiet. It gets louder, and considerably deeper and boomier than usual – a thick, resonant version of itself, with the brightness gone and the bass raised.
That is the whole explanation in one demonstration. You have just blocked the route that carries the ordinary airborne version of your voice to your ears, and what you are left listening to is a route you did not know you were using. It was there the entire time, mixed in underneath, and closing the other one off simply reveals it.
Like our content? Follow us for more.
You Hear Yourself by Two Routes and a Recording Has Only One
When anybody else listens to you, the sound makes one journey. It leaves your mouth, travels through the air, arrives at their ear and goes in.
When you listen to yourself, the same thing happens – and something else happens at the same time. The act of producing speech sets your head vibrating: the larynx, the jaw, the tissues of the throat and the bones of the skull all shake, and that vibration travels directly through the solid material of your head to the hearing apparatus on both sides. It does not go out into the room at all.
So your experience of your own voice is two signals added together, one through the air and one through your own structure, and it is the only sound in the world you hear that way.
A microphone is in the room. It can only ever pick up the first one. Which means a recording of your voice is not a poor recording – it is an accurate capture of the half you have never heard on its own.
Bone Conduction Strongly Favours the Low Frequencies
The two routes do not carry the same thing, and that is where the mismatch comes from.
Sound travelling through air into an ear arrives with its balance of high and low frequencies broadly intact – that is what the ear is set up for. Vibration travelling through bone and soft tissue does not behave that way. Dense material transmits low frequencies efficiently and progressively damps higher ones.
So the version arriving through your head is not just a quieter copy of the version arriving through the air. It is a differently shaped copy, with the bass largely preserved and the upper range substantially reduced.
Which means one of the two signals you have been hearing all your life is systematically bass-heavy, and it has been mixed in with the other one at a level you have no way of separating out.
So the Voice in Your Head Has Bass That Does Not Exist Outside It
Add the two together and the result is a voice with more low-frequency content than the one leaving your mouth.
That composite is your reference. It is what your voice sounds like, as far as you are concerned – the only version you have ever had sustained access to, formed before you could speak and reinforced every day since by everything you have ever said.
And it does not exist anywhere outside your head. Nobody has heard it. No recording has captured it. There is no device you could point at yourself that would produce it, because a substantial component of it never enters the air.
You have therefore spent your life with a private and slightly flattering reference copy, and the first time you hear the public version you compare it against that.
Which Is Why It Sounds Thin Rather Than Merely Different
People are quite specific about what is wrong with a recording of themselves, and the complaint is nearly always the same: it is higher, thinner, weaker, more nasal, somehow younger or less substantial than expected.
Every one of those descriptions is what you would predict from removing a bass-heavy component from a mixture. Take away the low end of anything and it sounds thinner and higher. The pitch has not changed at all – the recording and your head contain exactly the same note – but the balance has, and the ear reports a change in balance as a change in character.
That is the useful part of the explanation. The reaction is not vanity and not an illusion. Something measurable has actually been removed, and the version you are objecting to really is missing something that was present in the only version you knew.
Which Also Explains Why Singers Wear Monitors
Anybody who performs with amplification runs into this as a practical problem rather than a curiosity.
A singer on a stage is hearing their own composite – air plus skull – while the audience hears only the air part through a system that may be louder, differently balanced and some distance away. The two bear little relation to each other, and the performer has no way of knowing what is reaching the room.
Hence monitors: a dedicated feed of the external sound, played back to the performer close enough to dominate what they are hearing. The point is not volume. It is to replace a reference that is private and misleading with one that corresponds to what everybody else is getting.
Singers describe getting used to this as a very difficult adjustment, because the feed sounds wrong in exactly the way a recording does, and they have to learn to pitch and project against a version of themselves they do not recognise.
There Is a Second Effect and It Is Not Acoustic at All
The physics accounts for most of it and not all of it. There is a separate component that is about self-image rather than sound.
A voice is strongly bound up with identity. People form a sense of how they come across, and hearing a recording delivers a quantity of information about themselves that they did not ask for and cannot adjust: accent, hesitancy, speed, habits of phrasing, the things they say without noticing.
This part has nothing to do with bone conduction. It would happen even if a recording were perfect, and it is why people often dislike recordings of themselves speaking far more than recordings of themselves coughing or laughing, and why the discomfort is strongest with their own speech and almost absent when listening to somebody else’s.
People Rate Their Own Voice Higher When They Do Not Know It Is Theirs
There is a result that separates the two effects rather elegantly, and it has been obtained more than once.
Take recordings of a group of people. Mix each person’s own voice in among a set of others. Ask them all to rate the voices for how pleasant or attractive they sound, without telling anybody which one is theirs.
People rate their own voice favourably – in several versions of this, more favourably than they rate the others, and considerably more favourably than they rate it when they know it is theirs.
Which is a clean demonstration that a good deal of the dislike is not about the sound. The same recording, the same ears, the same acoustic information, judged as pleasant when anonymous and unpleasant when identified. The acoustic mismatch is real and it explains why the voice sounds unfamiliar; the identification is what turns unfamiliar into unbearable.
Nobody Had This Problem Before About 1880
It is worth remembering how recent this experience is. For the whole of human history until the invention of sound recording, no person had ever heard their own voice from the outside. Not once, not ever, in any culture.
Which means the familiar modern wince is a side effect of a specific piece of technology, and the first generations to encounter it found it considerably more disturbing than we do. Accounts from the early decades of recording describe people being distressed rather than merely embarrassed by playback, and refusing to accept that what they were hearing was them.
They were not being unsophisticated. They were encountering, with no warning or frame of reference, a fact about themselves that no human being before them had ever had to absorb – and the mechanism above means they were right that it did not sound like them. It really did not. It was missing half the signal they had always heard.
The Same Route Is Why You Can Hear Yourself Chew
Bone conduction is not a curiosity that only applies to speech. It is running constantly and it explains a set of experiences that otherwise make no sense.
The sound of your own chewing, loud enough to make it hard to hear somebody talking across a table. The crunch of your own footsteps on gravel, which is louder to you than to anybody walking beside you. Your own breathing. The noise of brushing your teeth.
All of these are generated in contact with your head and travel through it rather than round through the air, which is why they are disproportionately loud to their producer and unremarkable to everybody else. It is also the principle behind headphones that sit on the bone in front of the ear rather than over the canal, which work by feeding vibration into the skull directly and bypassing the ordinary route altogether.
So the odd thing is not that a recording of your voice sounds wrong. The odd thing is that you have a second private hearing channel, you use it every time you speak, eat or walk, and until somebody played a recording back at you there was no way of finding out it was there.
Like our content? Follow us for more.